Up to 20,000 Hours of Real English Interview Video for AI Training
Foundation Model Datasets
Tags and Keywords
$55,300
About
Up to 20,000 Hours (Growing Daily) of Fully-Consented Real Online Job Interview Video in English | Many Accents & Diverse Speakers (Africa, SEA, South Asia, LatAm + More) | AI Training Data | Video+Audio + Timestamp-Aligned Transcripts | Question/Context Descriptions | Global Coverage
A large-scale dataset of up to 20,000 hours (growing daily) of real online job interview video in English, featuring natural, non-scripted interview responses from a highly diverse speaker base across many regions and accent groups — including Africa, Southeast Asia, South Asia, Latin America, North America, Europe, and more.
All participants explicitly opt in (fully consented) for their data to be used for AI training and shared under controlled licensing.
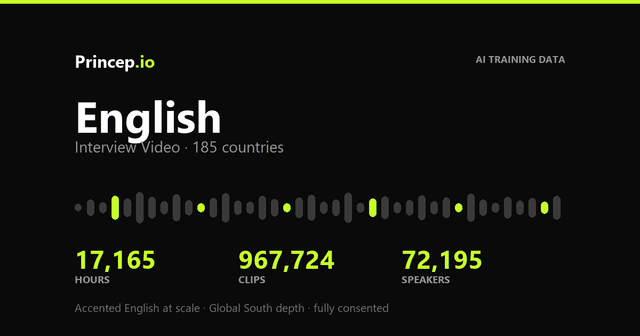
This is a living dataset: new recordings are added daily, so total hours increase over time (current total: 18,538 hours as of 26 August 2026, of which 17,166 hours are English).
Each clip is primarily single-speaker (candidate-focused), making it highly valuable for training models on authentic, real-world monologue speech in interview conditions.
Unlike staged or scripted recordings, this dataset captures authentic interview behavior — spontaneous phrasing, pauses, disfluencies, turn-taking, and real-world device variability. The video modality adds valuable capture signals that improve model generalization to production environments.
Key Features
1) Accent Diversity at Scale (Underrepresented Accents Included)
Designed for real-world robustness with broad English accent coverage:
- Diverse regional accents and speech patterns
- Variation in pronunciation, rhythm, speech speed, and vocabulary
- Strong coverage of accents often missing from public datasets (Africa, SEA, South Asia, LatAm)
2) Real Interview Video (Non-Scripted, Natural Speech)
All sessions come from genuine interview-style Q&A, capturing:
- Natural disfluencies (hesitations, self-corrections, fillers)
- Realistic interview pacing and tone
- Authentic response structure under real interview conditions
3) AI-Ready Packaging (Video + Transcript + Context)
Each session can include synchronized assets such as:
- Video with embedded audio (online interview capture)
- Timestamp-aligned transcripts (segment/sentence level)
- Question prompts, verbatim, on 85% of answers; question type/category where the employer configured one (20%)
- Technical and quality metadata (duration, device/channel signals)
Supports tasks including:
- Audiovisual speech recognition
- Lip/audio alignment research
- Speech modeling
- Multimodal conversational understanding
4) Real-World Capture Conditions
Video reflects realistic online interview environments:
- Mobile and desktop capture
- Consumer-grade device cameras and microphones
- Mostly indoor environments with natural lighting/background variation
- VoIP-style audio characteristics and device differences
5) Fully-Consented & Commercial-Ready
- Explicit opt-in consent for AI training and controlled dataset sharing
- Packaged for smooth integration into ML pipelines and enterprise procurement workflows
6) Continuously Expanding Library (Daily Updates)
- New recordings added every day
- Monthly intake: 3,000–4,200 new hours (June 2026: 4,165 h; July 2026: 4,220 h)
- Custom collection to brief: language, region, job family or question set — capacity on request
- Current total: 17,166 hours of English; 18,538 hours across the full catalogue (26 August 2026)
- Updated releases available upon request
Use Cases
- Multimodal AI training (video + audio)
- Audiovisual speech recognition and robustness benchmarking
- ASR / speech-to-text with diverse accents
- Multimodal evaluation under real capture conditions
- Accent robustness testing across regions
Delivery Format (Typical)
- Video files (with embedded audio)
- Timestamp-aligned transcripts
- Question/context descriptors + metadata schema
- Documentation (data card, release manifest, usage notes)
 TRUST
Loading...
$55,300
Download Dataset in VIDEO Format
Recommended Datasets
Loading recommendations...